Building a Canonical Data Model for Multi-Source Integration
Explores translators, middleware and point-to-point comparisons, plus a worked Customer mapping and governance for a canonical data model.
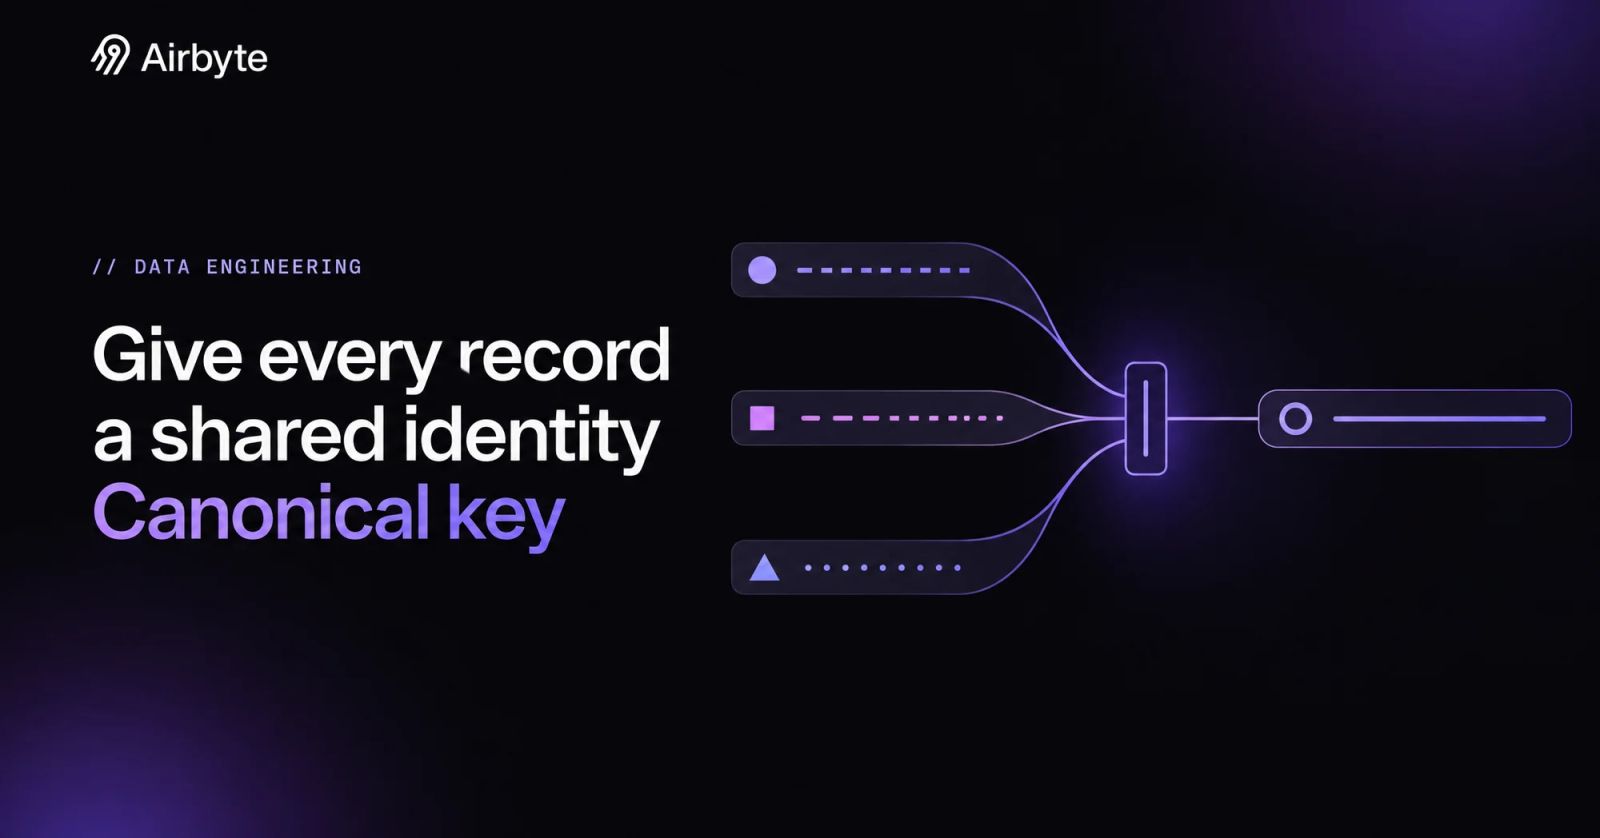
A canonical data model is a shared, application-independent data format, made up of entities, attributes and relationships, that every integrated system translates into when it sends and out of when it receives, instead of translating to each other. With every system talking to every other, it cuts translators from n(n-1) point-to-point mappings to 2n, but the central model needs governance and can become a brittle bottleneck. A canonical data model earns that cost only when you scope it to a few core shared entities with small, federated ownership. That scope tells you whether your system count justifies one, which entities to model first and how to version it without stalling every team.
Summary
- Count your systems first: direct integration needs n(n-1) translators when every system talks to every other, a canonical model needs 2n, and the two break even at three systems.
- Scope the model to the handful of entities that cross system boundaries, usually Customer, Product and Order, and leave everything else in the source systems.
- Map each source field by field into the canonical entity, write down every conflict you resolve, and keep each source ID in a crosswalk.
- Version the canonical schema with additive changes only: new fields get defaults, renames become add-then-deprecate, and removals wait for a major version.
- Give each core entity one accountable owner inside a small federated council, and let domain teams keep their own models behind translation layers.
Learn more about Hybrid Deployment
What Is a Canonical Data Model?
A canonical data model is an extra level of indirection between the data formats of individual applications. Each application must produce and consume messages in the one common format rather than in any partner’s native format, so a system only ever needs to know its own format and the canonical one.
A canonical model holds a deliberate subset of the source schemas, never their union. If your CRM Account object carries a long list of standard and custom fields and your ERP has its own long list of Business Partner attributes, merging them yields a model nobody can reason about.
That distinction shows up as two kinds of messages. Public, canonical messages travel between systems; private, application-specific formats stay inside each application. Your CRM keeps its picklists and custom objects, and the ERP keeps its account groups. The canonical layer agrees only on the shared core, so keep that core small: a model that grows past it stops being useful and becomes a project of its own.
How Does a Canonical Data Model Work?
The sending system emits data in its own format, a translator converts it into the canonical format, and middleware carries the message to each receiver, where a second translator converts it into the receiver’s format. This flow separates application formats, but you must maintain translation at both ends.
Message Translators Convert Each Source to the Canonical Format
Each system gets two translators: an inbound one that maps its native records into canonical form, and an outbound one that maps canonical records back into its native shape. Six systems therefore need twelve translators, and a seventh adds exactly two, regardless of how many systems already participate. The Message Translator plays the same role in messaging that the Adapter pattern plays in object design: it converts one interface into another so a component can be used in a different context.
When the billing system renames a column, only billing’s translators change, and the CRM and ERP translators stay untouched. The price is that every message is translated twice, once at the source and once at the destination, so the canonical model adds latency and code paths that a direct mapping would skip.
Middleware or an ESB Carries Canonical Messages Between Systems
Translators produce the canonical messages, and middleware moves them and decides where they go. A Message Bus in Enterprise Integration Patterns combines a common data model, a common command set and messaging infrastructure, and a Message Router decouples a message’s source from its final destination. A Messaging Gateway sits inside each application and hides the messaging code behind domain methods, so application developers call something like GetCreditScore instead of writing to a queue, which keeps messaging code out of application logic.
In practice the carrier might be an ESB, a Kafka cluster, or, in an ELT architecture, the warehouse itself. When raw source tables land in Snowflake or BigQuery and dbt models reshape them, the staging models act as inbound translators and the canonical marts act as the shared format. The sender never needs to know who reads the Customer table, which is the decoupling the pattern promises, and the schema those readers rely on is what holds it together.
The Canonical Schema Defines Shared Entities and Attributes
The schema is the contract both kinds of translators target. For Customer, it names the canonical key, the attributes every consumer can rely on, their types, and the rules for values such as country and currency. For Order, it defines the relationship back to Customer through the canonical key, never through a CRM or ERP identifier.
Give the canonical Customer its own surrogate key plus a crosswalk that records which CRM, ERP and billing IDs map to it. With identity established, choose one representation for each type so translators produce consistent values. Use an ISO country code instead of a mix of names and codes, and uppercase three-letter ISO 4217 currency codes even where a source such as Stripe sends lowercase ones.
A change to the canonical Customer schema touches every translator that reads or writes Customer, so one attribute change can require a coordinated update, test and deployment. The more the schema covers, the more often that coordinated release happens, which is why the question of when to build one comes down to how much change you expect at the center.
When Is a Canonical Data Model Worth Building Instead of Point-to-Point Integration?
Build one when several systems exchange the same entities, when source formats change more often than the shared business meaning, and when one group can own the shared definitions. Skip it when two or three systems exchange data, because the canonical layer then costs as much as it saves.
With every application talking to every other, the published translator counts are 2 direct versus 4 canonical for two applications, 6 versus 6 for three, and 30 versus 12 for six. Those counts follow n(n-1) for direct translation and 2n for the canonical approach, so the canonical model loses at two systems, ties at three and pulls ahead from four on. If only the CRM feeds the ERP and the ERP feeds billing, you have two connections, and the full-mesh calculation does not justify a shared model.
Volatile application formats favor a canonical model, because each change stays inside one translator. Volatile shared semantics hurt it, because a change to what “active customer” means hits every translator at once. If no team will own the Customer definition, settle disputes and publish versions, the model drifts into whatever the last integration needed, and you are back to point-to-point with extra hops.
A canonical model is one of several tools for sharing data, and another approach sometimes fits better:
These approaches combine more often than they compete. An MDM hub can publish the golden Customer in canonical form, and a data mesh still needs agreed definitions for the few entities that cross domains. The risk in every combination is the same: the shared layer quietly grows until it tries to describe the whole enterprise.
What Breaks When a Canonical Data Model Tries to Cover the Whole Enterprise?
An enterprise-wide canonical model breaks in three ways at once: it becomes too rigid to change, it fills with fields that fit no one, and every team ends up waiting on the group that owns it. The model becomes a God Object, one definition every system depends on and no team can safely change. Teams freeze the shared interchange format and work around it as their needs change. Sales and support can disagree both about which customers exist and about what shared attributes mean, so adding fields alone cannot reconcile their models.
To satisfy every consumer, schema designers make nearly everything optional, add flags whose meaning depends on the source, and collect attributes only one system uses. Consumers can no longer trust that a populated field means the same thing in every record, which defeats the reason for a shared format. A central modeling team that must approve every change also becomes the queue every project waits in, so ambiguous fields and approval delays compound each other.
Keep the canonical model and shrink its reach:
- Core-entity scope: The canonical model covers only the entities that cross boundaries, and each team decides whether to pull them into its own context.
- Federated council: Each core entity has one accountable owner, and a council of domain and platform owners sets global rules such as key formats and code lists. Under data mesh governance, that federated group models the elements that cross domain boundaries instead of one global canonical model.
- Bounded contexts: A bounded context is a boundary inside which a term means exactly one thing. Each domain keeps its own model of Customer inside its context and maps to the canonical form only at the edge.
- Anti-corruption layers: A translation layer at each boundary converts canonical data into the domain’s own terms, so a change in the shared model never leaks into a domain’s internal design.
Run governance checks in code so the council does not become another approval queue, and use lineage and catalog metadata to identify pipelines that read each canonical entity. The OpenLineage specification includes ownership facets for datasets and jobs, so reviewers can identify the teams responsible for downstream consumers. The Open Data Contract Standard defines contract status values such as proposed, active, deprecated and retired. Use those owners and statuses to review each mapping before consumers depend on it.
How Do You Map Source Systems Into a Canonical Data Model?
Map sources one entity at a time, starting from the entity most systems share, and resolve every conflict explicitly in the translator, never silently in a consumer. Five steps cover the work:
- Scope the entities. List which entities cross system boundaries and which consumers need them. Customer and Order usually qualify, while internal workflow objects do not.
- Choose a base. A published standard saves design time where one fits. In healthcare, the HL7 FHIR Patient resource is marked normative, with repeating identifier, name and telecom elements that already handle a person with several IDs and contact points. In travel, OpenTravel is rebuilding its standards around offer and order, with an object model exchangeable in JSON or XML. Without a standard, derive the model from the system of record for the entity, often the ERP, or design from scratch around consumer needs.
- Design the schema. Define the canonical key, attribute types, code lists and relationships. Decide nullability on purpose, because every optional field is a question each consumer has to answer.
- Map field by field. For each source, write the mapping and the rule that resolves each conflict, then implement it as that source’s inbound translator.
- Validate. Compare row counts and key coverage per source, test conflict rules on real edge cases such as person accounts and deleted customers, and fail the load when a source sends a value outside the code list.
A Customer entity drawn from Salesforce as the CRM, SAP Business Partner as the ERP and Stripe as billing shows how much each source disagrees with the others:
Each resolution in that table is a decision someone has to own. When lifecycle_status gets a fifth value next year, that change has to reach every consumer without breaking the ones that only know four.
Versioning is where scoped models stay healthy. Make every change additive by default: a new field gets a default value, a rename becomes a new field plus a deprecated old one, and a type change becomes a new field. Under the Avro specification, a reader whose schema has a field with a default fills it in when older data lacks the field, and signals an error when no default exists, so a new field without a default breaks any reader that meets older data lacking it. Register canonical schemas in a schema registry and set compatibility to BACKWARD_TRANSITIVE for canonical subjects, because the plain BACKWARD mode checks a new version only against the latest one, while canonical data gets replayed against much older versions. FULL_TRANSITIVE is stricter and suits entities that both old producers and old consumers keep touching. With JSON Schema, decide early between open and closed content models, because that choice changes which additions count as compatible.
Deprecation needs a window measured in consumer migrations, not calendar weeks. Mark the field deprecated in the schema and the contract, find every reader through lineage, and remove it only in the next major version after the last reader has moved. A deprecated field nobody tracks never gets removed, and that is how a lean canonical model gets its first layer of dead weight.
How Does Airbyte Help With Canonical Data Model Integration?
Airbyte handles the replication half of this architecture and leaves the model design to you. It moves raw records from your CRM, ERP and billing systems into your warehouse or lake through 700+ connectors, with CDC for databases that avoids locking production tables. Schema change detection lets you propagate new source columns automatically or approve them first, and breaking changes such as a removed primary key or cursor pause the connection for review before they reach your staging models.
The canonical mapping happens downstream. Airbyte’s dbt integration runs post-sync models, and your per-source staging models become the inbound translators from the mapping table above. You still decide the canonical key, the crosswalk, the status enum and the conflict rules; no connector makes those calls.
Airbyte provides RBAC, audit logging and column selection for replication workflows; your team still governs access to destination tables and downstream models. The same governed, current Customer and Order tables that feed dashboards can feed AI applications, including clients that connect over MCP.
What Should a Canonical Data Model Cover First?
Start with identity, before any attribute. The first version of the canonical Customer should contain the surrogate key, the crosswalk to every source ID and a lifecycle status, and nothing else until two consumers ask for the same additional field. Identity is the part every team needs and nobody can build alone, while attributes are where domains legitimately disagree. If the crosswalk is right, each domain can join back to its own richer model; if it is wrong, no amount of attribute modeling saves the integration.
With Airbyte supplying raw inputs, test your crosswalk against source changes before extending the shared contract. Use post-sync models to validate key coverage and conflict rules before downstream consumers depend on a new field.
Get a demo to see how Airbyte feeds every source into your canonical model.
Frequently Asked Questions
What does canonical mean in databases?
Canonical means the agreed, authoritative form of something when several forms are possible. A canonical date format, for example, is the single representation every system writes so that two dates can be compared without guessing at their format. In data modeling, the canonical form of an entity is the representation every participant accepts as the reference, even when each system stores its own variant internally.
Is a canonical data model the same as Microsoft’s Common Data Model?
No, the canonical data model is an integration pattern: you design the shared format for your own systems. Microsoft’s Common Data Model is a specific published set of standard entities, such as Account, Contact, Lead and Opportunity, that originated in Dynamics 365 and is implemented in Dataverse and used across Power Apps and Power BI. Microsoft’s published entities follow an additive-only versioning policy. You can adopt it as the base for your own canonical model, which works best when much of your estate already runs on Dynamics 365 and Dataverse.
Does a canonical data model work with event streaming platforms like Kafka?
Yes, and topics make a natural home for canonical contracts. A common layout puts all events for one aggregate, such as Customer, in one topic, because consumers rebuild state by replaying those events in order, and keys each message by the canonical customer ID. Each event can carry an envelope with an event type, so CustomerCreated and CustomerAddressChanged can share a topic. Keep internal domain events inside the producing service and publish separate integration events in canonical form after the transaction commits, so consumers never couple to a service’s internal tables.
Should a canonical data model be normalized or denormalized?
Keep the canonical layer normalized and build denormalized marts on top of it for analytics; messaging consumers do better with canonical entities that reference each other by key. Those references keep payloads small and give each fact one owner. The tradeoff is that a consumer needing customer details must call back or maintain its own copy. Events that carry full state avoid that call at the cost of larger payloads and more copies to keep consistent. Analytics consumers want denormalized dimension tables, such as a single dim_customer row that combines CRM, billing and marketing attributes, because business users expect fast dashboards, and star schemas are built for that performance and ease of use.
How do I retire a canonical data model that has become a bottleneck?
Retire it incrementally with a strangler fig approach instead of a rewrite. Pick one domain, give it its own bounded context and model, and put a translation layer between that context and the old canonical model so the remaining consumers see no change. Run old and new paths in parallel and compare their outputs until they match within tolerance, then move consumers over one at a time. Repeat domain by domain, and keep a small shared kernel, typically the customer identity and crosswalk, as the one piece every context still agrees on.
Integrate with 700+ apps using Airbyte
Move data from 700+ sources into warehouses, lakes, and beyond. Set up pipelines in minutes with pre-built connectors and the Connector Builder.