What ETL Tools Help You Manage Data Across Hybrid and Multi-Cloud Environments?
Compare ETL tools built for hybrid and multi-cloud environments, with notes on deployment models, connector coverage, and data residency.
ETL tools with managed, hybrid, or self-managed deployment options can manage data across hybrid and multi-cloud environments when their connectors, control boundaries, and recovery behavior match each workload. You often choose between legacy ETL platforms that require substantial maintenance and custom integrations that consume engineering time. In the 2025 State of Analytics Engineering, 57% of respondents said they spend most workdays maintaining or organizing data sets.
The right ETL tool connects distributed systems, applies common schemas, and delivers governed data. It also makes residency, recovery, and cost tradeoffs visible.
TL;DR
- Choose ETL tools based on where records, credentials, metadata, and compute may run and whether required connectors are production-ready.
- Match each pipeline to a measurable freshness target, recovery plan, and schema-change policy.
- Compare managed cloud, hybrid deployment, and self-managed options across the full sovereignty spectrum.
- Test connector behavior, data transfer costs, and deployment migration with representative workloads before committing.
What Are the Main Challenges of Managing Data Across Hybrid Environments?
The main challenges are operational unreliability, security and compliance constraints, and unpredictable costs across fragmented systems.
You spread workloads across on-premises systems, Amazon Web Services (AWS), Azure, and SaaS tools for good reasons: cost control, compliance requirements, and avoiding vendor lock-in. The trade-off is fragmentation that breaks analytics when you need it most.
Operational Reliability
Data Silos Block Critical Business Decisions
Your teams spin up their own databases or SaaS apps. This creates isolated pockets of information. Your manufacturing team runs SAP on-premises, while sales operates in Salesforce, and marketing uses six different tools.
These silos block you from reconciling metrics across business units. When the board asks about customer lifetime value, you discover three different definitions of "customer" across your systems.
Latency Kills Time-Sensitive Operations
Moving terabytes between regions or providers saturates network links and delays downstream analytics. Cross-cloud queries often time out during peak processing windows. Refreshes over WAN links can time out during critical migration windows.
Healthcare bed-occupancy dashboards and airline gate operations may require updates measured in minutes, while finance reporting can often tolerate hourly or daily batches. The architecture should follow each pipeline's service-level objective (SLO).
For continuous replication, CDC reads database transaction logs and avoids repeated full-table scans. That reduces source load, but it introduces a retention dependency. If a connector remains offline longer than the source retains PostgreSQL Write-Ahead Log (WAL), MySQL binary logs, or SQL Server CDC records, it may need a new snapshot before replication can resume.
Batch pipelines remain appropriate for modeling-heavy reporting and large backfills. Production data on Snowflake Dynamic Tables shows a wide range of target lags, with nearly 20% below five minutes and more than 25% at 16 hours or longer. Set an explicit freshness requirement for each pipeline.
Schema Evolution Breaks Downstream Analytics
Source systems evolve independently. They may change field names, data types, or nested structures without warning. Keeping data models aligned becomes manual work that slows releases and introduces pipeline failures.
Compatibility policies let you accept, quarantine, or reject changes before they break consumers. For example, Avro can safely add an optional field with a default under backward compatibility, while adding a required field without a default is breaking.
You should evaluate table-format behavior separately. Table formats such as Apache Iceberg track fields by stable IDs, so a rename can remain a metadata-only operation instead of appearing as a drop-and-add.
Security and Compliance Create Architecture Constraints
Each environment enforces its own encryption, Identity and Access Management (IAM), and audit models, so coordinating General Data Protection Regulation (GDPR), Health Insurance Portability and Accountability Act (HIPAA), or System and Organization Controls (SOC) 2 controls across multiple clouds widens your attack surface. Cross-border data residency rules add another architectural constraint: financial services companies may need to keep certain data in regional data centers while analysts still need governed outputs for risk reporting.
HIPAA does not require electronic protected health information (ePHI) to remain in a hospital Virtual Private Cloud (VPC). The current Security Rule is technology-neutral.
You still need to assess the safeguards that apply to each workload. Encryption remains an addressable implementation specification.
Cost Management Becomes Unpredictable
Egress fees, redundant storage, and idle compute spike unexpectedly when pipelines copy full tables across clouds. Without fine-grained monitoring, you discover overruns only after the bill arrives.
What Makes an ETL Tool "Hybrid/Multi-Cloud Ready"?
A hybrid or multi-cloud ETL tool should document the differences between managed, hybrid, and self-managed operation, including feature availability in each model.
Deployment and Connectivity
Deployment Flexibility Across All Environments
You keep sensitive workloads close while pushing heavy processing to the cloud. Docker and Kubernetes support means your pipelines can move between AWS, Azure, Google Cloud, and your data center with minimal code changes.
Most managed hybrid products split into a vendor-operated control plane and a customer-operated data plane. The control plane stores configuration, schedules work, exposes APIs, and receives metrics. An agent or runner inside the customer network connects to private sources, executes extraction or data processing, and writes to the destination. Hybrid agents generally initiate outbound connections, but network and firewall requirements vary by product and feature.
Managed services handle much of the scaling automatically. Self-hosted deployments depend on your Kubernetes or virtual machine configuration, but they give you granular control over resource allocation, network routing, update windows, and source-local processing.
The platform should offer the required functionality in the selected deployment model. Verify feature availability before choosing a model. Connector support, credential storage, autoscaling, high availability, and migration between SaaS and hybrid modes vary. Changing deployment models may require a resync or a new project, depending on the product and configuration.
Connectivity That Eliminates Custom Development
Pre-built connectors reduce custom development, but they rarely eliminate it. They determine whether you spend months building custom integrations or days configuring existing ones. You need native support for legacy databases, modern data lakes, and hundreds of SaaS APIs.
Open-source frameworks often include connector development kits, which let you build required connectors while vendor roadmaps continue on their own schedules.
Production readiness requires connector-level verification beyond catalog size. For each required source and destination, verify snapshot and CDC support, deletion handling, and schema-change policy. Check cursor or log-position recovery, hybrid eligibility, credential placement, and API rate-limit behavior. Support can vary by connector, sync mode, and deployment path.
Processing and Governance
Processing Power for Complex Hybrid Workflows
Your platform needs the processing model that matches each workload. Nightly fact-table rebuilds can run alongside continuous CDC streams, but they have different scaling, recovery, and cost characteristics.
Networks can emit billions of call detail records (CDRs) and events per day. These volumes can exceed the capacity of ETL architectures that rely on full-table scans or single-node processing. Terabyte-scale log volumes from SAP and Oracle can overwhelm replication deployments with inadequate log retention, processing capacity, or Wide Area Network (WAN) throughput.
Use streaming CDC when freshness measured in minutes, heterogeneous sources, and continuous change capture justify operating transaction-log retention and replay controls. Use batch ELT when hourly or daily freshness is acceptable, data shaping is extensive, or backfills dominate. Managed zero-ETL can simplify supported same-cloud and same-region pairs, but freshness and data-shaping support vary by source, destination, and service configuration. Zero-copy sharing avoids duplicate storage in compatible environments, but cross-region reads can add recurring egress, latency, and security exposure.
Security and Governance Built In
Require encryption in transit and at rest, role-based access control (RBAC), audit trails, and region-specific processing where data sovereignty laws apply. Features such as column masking and hashing can support GDPR and HIPAA compliance programs without requiring you to implement every protection downstream.
For hybrid agents, trace how records flow through the system. Document where the system stores credentials and identify which metadata leaves the customer network. Credential placement varies by product and configuration. Some services use vendor-managed cloud systems, while others support local storage or customer-managed secret stores.
Consistent controls matter across deployment models, but a local data plane alone cannot establish sovereignty. Remote access from a third country can itself constitute a transfer. Map logs and telemetry field by field, restrict support access, keep encryption keys in-region where required, and document residual transfers.
Integration With Your Existing Workflow
The interface should match how your team works. Drag-and-drop user interfaces (UIs) let non-technical users move quickly, while APIs, Terraform providers, and SDKs let engineers embed pipelines into CI/CD workflows.
Evaluate more than authoring convenience. Determine whether your team can store and review connection configuration in Git, whether state and secrets remain separate from code, and how pipelines move from development to staging and production. Verify infrastructure-as-code coverage for sources, destinations, schedules, schema policies, and access controls. Then test rollback behavior when a connector update or configuration change causes a regression.
Downstream compatibility with your business intelligence (BI), ML, and observability tools ensures data flows into existing analytics workflows and avoids another integration challenge. Governed replication can also keep retrieval stores, agent context, and AI data products up to date.
How Do the Leading Tools Compare?
The best ETL tool for hybrid and multi-cloud work depends on your topology, operating model, and compliance requirements.
Deployment boundaries and integration requirements narrow the viable operating models before connector breadth or authoring convenience can determine the shortlist.
Which ETL Tools Work Best for Hybrid and Multi-Cloud Data Management?
Within those boundaries, the five platforms take different approaches to hybrid deployment models, connector maintenance, and warehouse integration. Compare each platform against your actual topology and the requirements it creates.
1. Airbyte: Open-Source Foundation With Enterprise Security
Overview: Airbyte’s open-source foundation supports several operating models. You can run Airbyte Cloud, use Airbyte Flex with customer-controlled data planes in your environment, deploy Airbyte Open Source, or use Self-Managed Enterprise when workloads require greater infrastructure control.
Airbyte has four relevant operational strengths:
- Cloud-managed orchestration with customer-controlled data-plane placement through Airbyte Flex.
- Extensible through a Connector Development Kit for custom sources.
- API-based configuration and orchestration through Airbyte Open Source and Self-Managed Enterprise deployment options.
- Batch and incremental replication across private and cloud endpoints.
Operational Considerations: Choose the deployment model based on network reachability, key ownership, update responsibility, and recovery objectives. A customer-operated data plane provides more control, but your team remains responsible for sizing its compute, storage, and high-availability configuration.
2. Fivetran: Fully Managed Simplicity
Overview: Fivetran runs the pipeline control plane and maintains its connectors. It offers managed, hybrid, and self-hosted replication options.
Fivetran has three relevant operational strengths:
- Automated schema drift handling.
- Vendor-maintained connectors and pipeline control plane.
- Managed, hybrid, and self-hosted replication options.
These capabilities suit teams that want vendor-managed operations while retaining a choice of data-plane placement.
3. Talend: Enterprise Governance Focus
Overview: Now part of Qlik, Talend offers commercial tools for cloud, on-premises, and customer-operated execution. Qlik retired Talend Open Studio, so you should not treat the former community edition as a current deployment path.
Talend offers two relevant operational strengths:
- Flexible deployment across hybrid infrastructures.
- Teams can evaluate integration requirements for big data platforms like Hadoop.
Talend also has two main considerations:
- Your team should test implementation and training requirements against its experience.
- Your procurement team should compare licensing requirements with team budgets and delivery timelines.
Before selecting a platform, validate whether the deployment boundary justifies the licensing and training responsibilities.
4. Informatica: Legacy Enterprise Integration
Overview: Informatica’s PowerCenter and Intelligent Data Management Cloud have powered enterprise integrations for decades.
Informatica offers three relevant operational strengths:
- Parallel processing for enterprise integrations.
- Deep mainframe connectivity.
- Metadata management and lineage tracking.
Informatica also has two main considerations:
- Test implementation effort and timelines against workload requirements.
- Evaluate pricing and procurement requirements against workload requirements.
Before selection, validate whether mainframe connectivity justifies the implementation effort and procurement requirements.
5. Matillion: Cloud Data Warehouse Performance
Overview: Matillion focuses on ELT for cloud data warehouses like Snowflake, BigQuery, Redshift, and Synapse. It pushes processing into the warehouse. This approach uses warehouse compute, so teams should measure performance and cost with representative workloads.
Matillion offers three relevant operational strengths:
- Visual job builder with native SQL support.
- Credit-based pricing aligned to task duration and type.
- Designed for major cloud warehouses.
Matillion has one main limitation:
- Warehouse dependence can create migration challenges.
Before selecting a tool, test whether warehouse dependence creates acceptable migration risk.
How Do You Choose the Right Tool for Your Hybrid Strategy?
Choose a tool by matching connector coverage, processing model, deployment boundary, compliance controls, cost units, and operating responsibilities to your systems and team.
Technical Fit
Inventory Your Integration Requirements
Map every system you expect to connect, including SaaS apps, on-premises databases, streaming logs, and Internet of Things (IoT) edge devices. Platforms with broad, native connectivity shrink integration time and protect your investment. Catalog breadth and curation vary by platform.
Electronic health record (EHR) systems, lab instruments, and claims processing still require careful mapping across Health Level Seven (HL7) and Fast Healthcare Interoperability Resources (FHIR) representations. Manufacturing companies require SAP CDC with recoverable delta queues. Financial services need rapid change capture with auditable replay.
Match Processing Capabilities to Business Requirements
If you need rapid fraud detection, choose platforms that treat streaming ingestion as core functionality. Batch-centric engines work for overnight reporting but introduce unacceptable lag for operational dashboards.
Match data-plane placement to regulated-record boundaries, private-endpoint access, and your team’s capacity to operate the runtime. Use fully managed SaaS when supported sources, moderate freshness requirements, and reduced operational work matter more than infrastructure control.
Zero-ETL and zero-copy serve narrower roles. They work best for supported same-region systems where limited data shaping and platform coupling are acceptable. Cross-cloud analytics, frequent schema changes, and multi-source business logic still require governed movement and data shaping.
Cost and Compliance
Evaluate Total Cost of Ownership
Self-hosted software offers raw infrastructure pricing and freedom to pause clusters at will. Managed services translate operational effort into subscriptions tied to billing dimensions such as active rows, credits, capacity, data volume, executions, or job duration.
Compare those units with your workload shape and its update patterns. Update-heavy tables can behave differently from append-only logs, and full-refresh processing consumes warehouse compute even when an ingestion vendor does not bill for unchanged rows.
Factor in egress charges whenever records cross providers or regions. Estimate monthly cost as transferred GB × provider rate. Calculate each path and direction separately.
Initial migration waivers do not cover ongoing multi-cloud traffic. Incremental loading, compression, source-local filtering, and push-down processing can reduce both transfer and compute costs.
Assess Compliance and Security Requirements
You may prioritize hybrid cloud primarily for data sovereignty reasons. Validate each workload against the applicable regulatory requirements and the security controls available in its selected deployment model.
Managed platforms may provide SOC 2 attestations and HIPAA-supporting controls, including business associate agreements (BAAs) where applicable. You must still validate the service configuration and your own compliance responsibilities. Self-hosted engines leave you responsible for hardening but provide finer-grained network isolation.
Align with Team Skills and Workflow
Drag-and-drop UIs lower barriers for analysts. Engineering-focused features, including API orchestration, Terraform modules, and custom connector SDKs, become critical as pipelines scale.
Match the operating model to the people who will own production changes. Confirm who owns connector upgrades, schema-policy changes, failed sync recovery, and custom connector maintenance before selecting a platform.
Open frameworks let you script, containerize, and version pipelines alongside application code. Your DevOps team may already know this workflow. That familiarity can make adoption smoother than learning proprietary interfaces.
What Are the Best Practices for Managing Hybrid Data Pipelines?
Manage hybrid data pipelines with centralized monitoring, joint cost and performance tracking, consistent security, automated schema recovery, sovereignty-aware routing, and shared dashboards.
1. Build Centralized Metadata and Monitoring
Collect detailed lineage, job metrics, and column-level statistics in a shared catalog. You can't troubleshoot what you can't see, so centralized visibility helps you identify which system or pipeline introduced a mismatch.
When you instrument pipelines with byte-level counters and latency SLOs, you spot anomalies early. Set alerts on both data volume and job duration. Either spike usually indicates unplanned full reloads or API throttling. When the chief financial officer (CFO) asks why revenue numbers don't match between systems, centralized lineage traces the problem back to its source within minutes.
2. Monitor Cost and Performance Together
Cross-cloud transfers generate substantial egress fees, especially when data volumes spike unexpectedly. Monitor throughput and spending in the same dashboard to catch overruns before they hit your budget.
Process data close to the source and ship only deltas or pre-aggregated results to reduce WAN traffic, cloud storage costs, and egress fees for high-volume daily ERP or IoT streams.
3. Implement Consistent Security Policies
Encrypt all data movement and route authentication through your existing identity provider. Each cloud platform has its own security model, but you need consistent security policies across environments.
Connect to enterprise single sign-on (SSO), so removing one engineer's access works across all clouds. Enforce identity provider (IdP)-only authentication for verified company domains, automate provisioning and deprovisioning through System for Cross-domain Identity Management (SCIM), and disable local accounts where the platform supports it. Inconsistent IAM practices create audit problems faster than almost any other security weakness.
4. Automate Schema Evolution and Recovery
Use explicit compatibility policies and automated re-sync controls to prevent schema drift from breaking downstream queries. Data sources change without warning, but accepting every change automatically can be as dangerous as rejecting all changes.
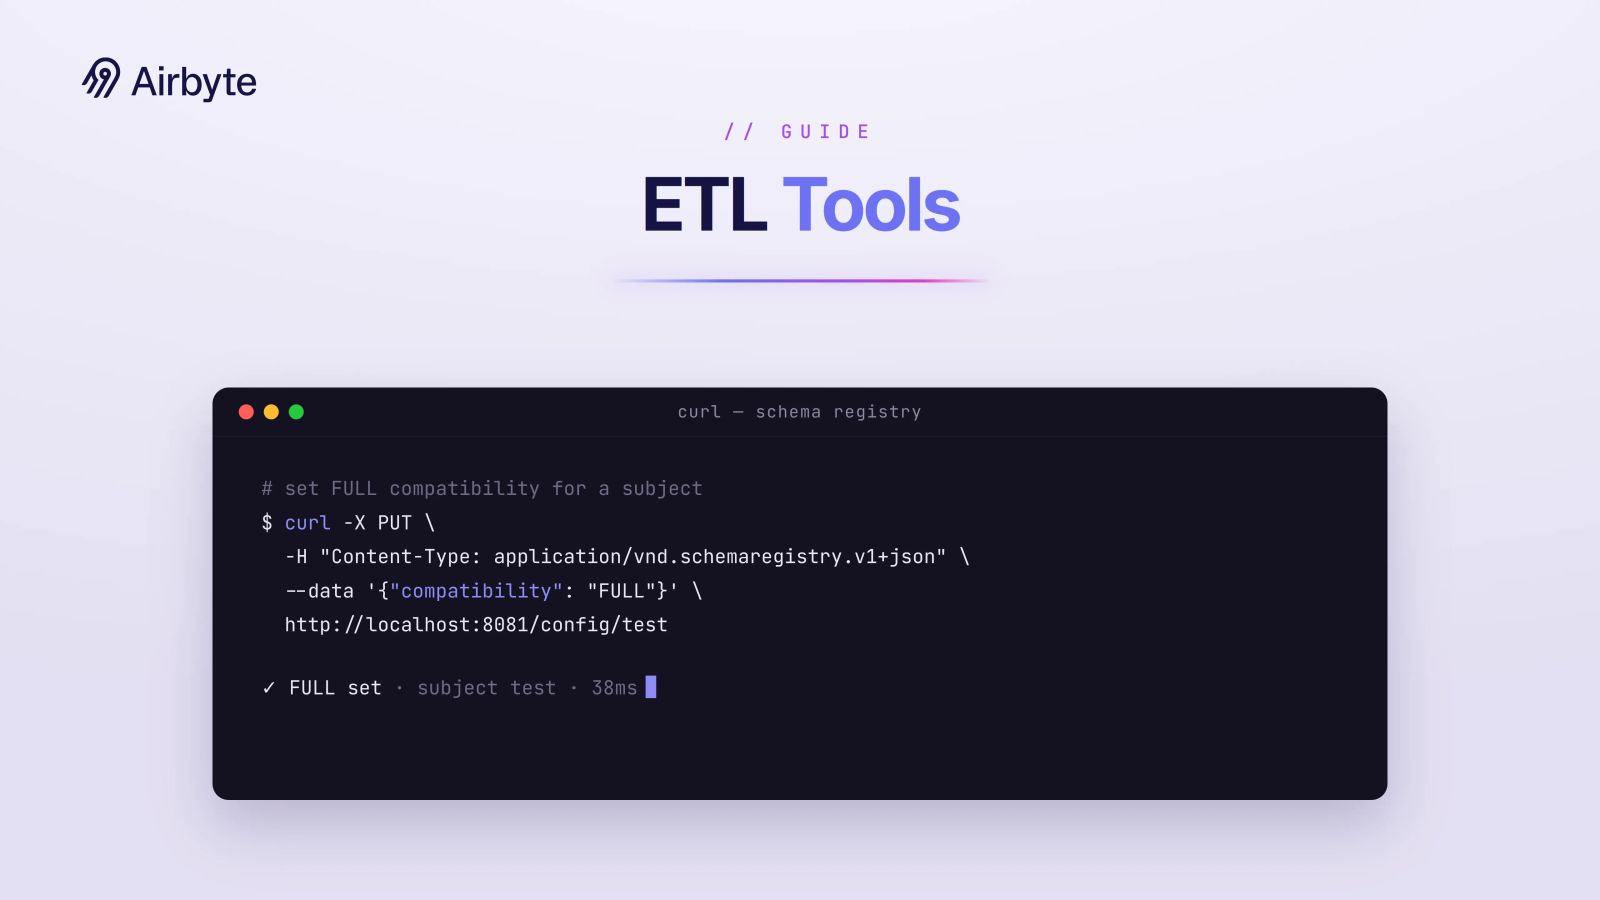
For event streams, set compatibility per subject and test proposed schemas before registration. This example sets Confluent Schema Registry to FULL. The setting allows only changes that are both backward and forward compatible:
<pre><code>curl -X PUT -H "Content-Type: application/vnd.schemaregistry.v1+json" \
--data '{"compatibility": "FULL"}' \
http://localhost:8081/config/test</code></pre>For PostgreSQL CDC, monitor logical replication slots before retained WAL fills storage or the slot becomes unusable:
<pre><code>SELECT slot_name, plugin, active, wal_status, safe_wal_size,
       restart_lsn, confirmed_flush_lsn
FROM pg_replication_slots;</code></pre>
Treat unreserved as an urgent retention warning and lost as a signal that the connector must reinitialize from a fresh snapshot. Configure retention to exceed expected connector downtime, and use heartbeats on low-traffic databases so acknowledged log positions keep advancing.
Build idempotent replay capabilities so retries never duplicate records. Deduplicate by a stable business key and event version before a MERGE. Snowflake and BigQuery reject nondeterministic updates when multiple source rows match one target row. Preserve source offsets or transaction identifiers so recovery can distinguish a replay from a new change.
5. Respect Data Sovereignty Requirements
Tag sensitive datasets and route them to region-specific storage from the start. Some data must remain within particular jurisdictions while non-regulated information can take cost-effective paths.
Build this routing logic early. Your company may acquire new cloud footprints or face additional compliance requirements. Regional data planes let you keep raw data local while running global analytics policies.
6. Create Visual Management Tools
Unify the monitored categories from separate platform logs into one view with clear alert thresholds. Use the thresholds below as starting points, then tune them to each pipeline’s SLO, baseline, and observed workload data.
How Do You Build a Future-Proof Hybrid Data Strategy?
Build a portable, future-proof hybrid data strategy by proving one useful pipeline, owning the integration layer, requiring portable deployment controls, and testing regulatory exit paths. Your topology should follow business and recovery needs while accounting for vendor limits.
Prove and Control the Architecture
Prove one high-impact pipeline first, then control the integration logic, lineage, and recovery rules as you expand.
Start With One High-Impact Use Case
Pick a specific business problem that demonstrates clear value. Maybe it's pulling order data from your on-premises ERP into BigQuery for same-day revenue reporting. Or connecting hospital EHR systems to provide timely dashboards for bed occupancy.
Validate your latency targets, security policies, and cost controls on this focused use case before expanding. This approach exposes problems in lineage tracking and access control while stakes remain manageable.
Own Your Data Integration Layer
When you control the logic that extracts from every source, standardizes schemas, and delivers data where teams need it, you create one auditable pipeline everyone can build on. The integration layer establishes common definitions, lineage, and recovery rules.
Require Portable Capabilities
You need portable deployment, security, and scaling capabilities, plus a tested exit path.
Demand Three Critical Capabilities
Require three capabilities as a practical portability baseline:
- Deployment freedom: Cloud, containers, or on-premises with the functionality your workload requires
- Security controls: Governance embedded across deployment models
- Elastic scaling: Handle both batch and streaming workloads with defined operational responsibilities
Open-source foundations can provide deployment control and portable integration logic. Open storage formats still create some lock-in. Apache Iceberg can make data readable by multiple engines. Catalog behavior, governance policy, credential vending, and unsupported format features can still tie an architecture to particular services. Cross-cloud egress can do the same.
Choose openness where it produces an operational exit path. Test that path by exporting configuration, rebuilding a representative pipeline, switching compute engines, and measuring catalog and network behavior before a contract or regulatory event forces the move.
Prepare for Regulatory Change
Plan for changing regulatory scope by testing how workloads move between deployment models.
Plan for Regulatory Evolution
Compliance requirements change faster than infrastructure refresh cycles. The EU Digital Operational Resilience Act (DORA) is in active enforcement and requires complete and tested exit strategies for information and communication technology services that support critical or important functions. The requirement applies within that scope, not to every cloud contract.
If HHS finalizes the proposed HIPAA Security Rule, it would strengthen encryption and network-segmentation requirements.
Regulatory scope also varies by jurisdiction. China’s Personal Information Protection Law (PIPL) permits cross-border transfers through security assessments, certification, standard contracts, and other approved conditions. The 2024 CAC provisions also provide exemptions and volume-based thresholds.
Choose platforms that support multiple deployment models within the same product. Then verify the cost and technical conditions for moving between them. Start with hybrid deployment for compliance-sensitive data, expand to full cloud for non-regulated workloads, or tighten controls when requirements demand it.
How Airbyte Flex Helps Build Your Unified Data Strategy
Airbyte Flex uses a hybrid control plane for hybrid deployment: Airbyte operates the control plane, while you operate the data plane in your environment. Configure the deployment by classifying control-plane metadata and defining support access.
Airbyte’s open-source foundation and deployment options let you keep integration logic visible across operating models. This can reduce some forms of deployment lock-in when teams can export configuration and rebuild pipelines, although you should still test connector state, secrets, and recovery behavior before changing deployment models.
Airbyte supports 2M+ pipelines daily and 26B records daily, and 18% of the Fortune 500 use the platform. A study reported a 239% ROI.
Where Should You Start?
Start with a representative Airbyte pipeline that tests your deployment boundary, recovery requirements, and transfer costs. Get a demo to see how Airbyte Flex deploys the replication connector catalog in your boundary.
Frequently Asked Questions
What Is a Hybrid ETL Tool?
A hybrid ETL tool moves data across customer-controlled infrastructure, public clouds, and SaaS systems. It may separate a vendor-operated control plane from a data plane that runs in your environment.
How Should You Compare Hybrid ETL Deployment Models?
Document the operating boundary and responsibility split for each model. Verify who manages upgrades, scaling, high availability, recovery, and connector state.
When Should You Use CDC Instead of Batch ELT?
Use CDC when a pipeline needs continuous change replication and the source can retain transaction logs long enough for recovery. Use batch ELT when hourly or daily freshness is acceptable, data shaping is extensive, or large backfills dominate.
Does an In-Boundary Data Plane Guarantee Data Sovereignty?
An in-boundary data plane alone cannot guarantee data sovereignty. Telemetry, metadata, support access, credentials, and encryption keys may still cross jurisdictions.
How Should You Test an ETL Tool Before Committing?
Run a representative workload that includes schema changes, deletions, connector downtime, replay, and a large backfill. Measure freshness, recovery time, source load, compute use, and cross-region transfer cost.
Integrate with 700+ apps using Airbyte
Move data from 700+ sources into warehouses, lakes, and beyond. Set up pipelines in minutes with pre-built connectors and the Connector Builder.