Cross-Border Data Transfer Compliance: Global Enterprise Guide
Master global data transfer compliance with GDPR, LGPD & emerging regulations. Learn unified architectures for sovereignty without sacrificing capability.
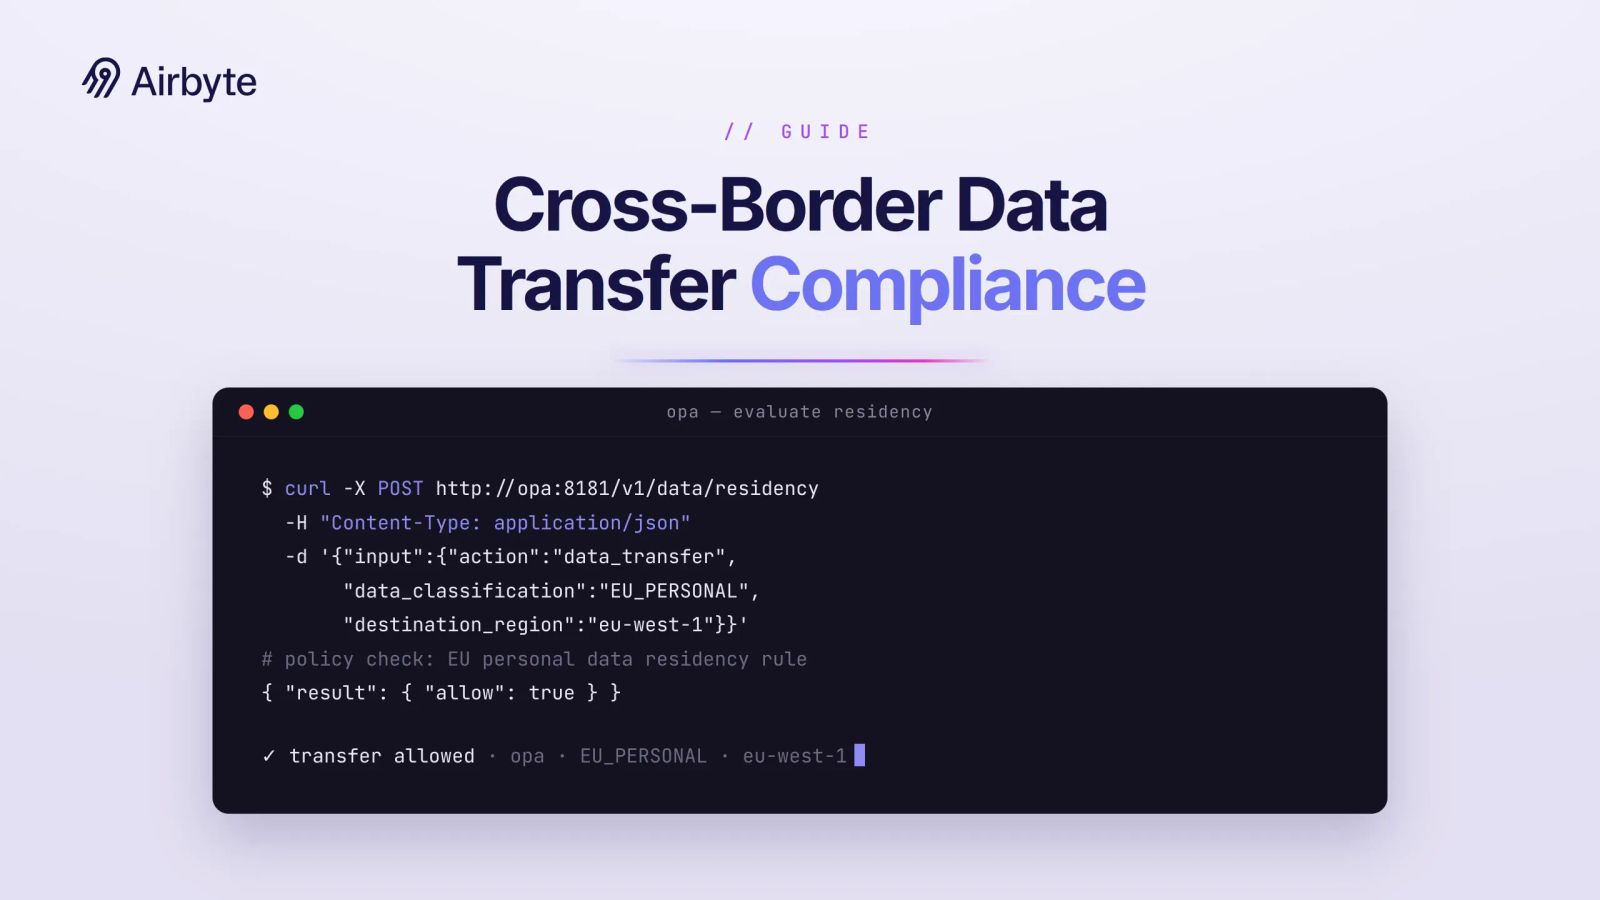
Every overnight analytics sync or customer support lookup moves personal data through multiple jurisdictions. The applicable requirements may include the General Data Protection Regulation (GDPR) in the EU, sectoral rules in the US, Brazil's General Data Protection Law (LGPD), or the emerging Global Cross-Border Privacy Rules (CBPR) framework.
Compliance in cross-border data transfers generally requires two forms of proof. You must show that data left one country only under a recognized legal mechanism. You must also show appropriate safeguards, such as encryption, auditing, and contractual measures, in line with the applicable framework. Your architecture determines whether you can produce that evidence; policy binders alone cannot.
TL;DR
- For cross-border data transfer compliance, match every transfer to a recognized legal mechanism and document the safeguards that support it.
- Use a unified control plane with regional data planes to centralize policy while keeping regulated processing in-boundary.
- Pin compute, storage, logs, backups, encryption keys, support access, and failover destinations to approved regions.
- Maintain auditable inventories, lineage, policy decisions, recipient records, and tamper-evident logs for every transfer.
- The same boundary question now determines where AI and agent workloads can read first-party data.
What Global Frameworks Govern Your Cross-Border Data Transfers?
The EU's GDPR, U.S. sectoral statutes, Brazil's LGPD, and the Global CBPR system each impose distinct prerequisites, and they rarely align. An international data transfer may implicate one or more of these privacy regimes, depending on the exporter, recipient, data subjects, data type, and processing context.
GDPR and European Economic Area Requirements
GDPR requires that personal data maintain its protections wherever it travels. Adequacy decisions, Standard Contractual Clauses (SCCs), Binding Corporate Rules (BCRs), and documented Transfer Impact Assessments (TIAs) are part of the GDPR framework for data movement. Adequacy decisions confirm an "essentially equivalent" level of protection. SCCs and BCRs generally require a documented assessment showing that the exporter and importer can maintain essentially equivalent safeguards in practice.
Mechanism selection should start with the destination and recipient. Verify whether an adequacy decision covers the country, sector, and specific recipient before relying on it. If it does not, select another applicable GDPR Chapter V mechanism.
You may use SCCs between separate organizations or within a corporate group, while approved BCRs apply to eligible intragroup transfers. When you use Article 46 safeguards, document the assessment of destination law and practice and adopt supplementary measures where necessary. You must verify that a U.S. recipient relying on the EU-U.S. Data Privacy Framework currently holds certification for the relevant data and purposes.
Your operational review must also maintain a processor and subprocessor inventory covering cloud hosting, logging, support, and telemetry providers. For each entity, record where it processes data, whether personnel can obtain remote access, who controls encryption keys, and whether the importer needs cleartext access. Encryption becomes a stronger supplementary measure when you or an entity in the European Economic Area (EEA) or an adequate jurisdiction retain exclusive control of the keys. Transfer risk remains when the importer can access plaintext or keys.
An approval workflow classifies the dataset, confirms the recipient and purpose, selects the transfer mechanism, completes any required TIA, validates key custody and support access, and records the decision in the transfer inventory before your pipeline runs. Reassess the approval when the recipient, subprocessors, destination law, processing purpose, data categories, or technical safeguards change.
United States Sectoral and National Security Rules
The United States has no single complete federal privacy statute. Instead, the Health Insurance Portability and Accountability Act (HIPAA), Gramm-Leach-Bliley Act (GLBA), and state-level statutes like the California Privacy Rights Act (CPRA) govern specific data types. The DOJ Bulk Data Rule restricts specified outbound transfers of sensitive personal data to countries of concern, with requirements such as encryption, risk reviews, and record-keeping.
Begin implementation by classifying health, financial, biometric, precise geolocation, genomic, other 'omic, government-related, and covered identifier data separately. Avoid applying one generic U.S. label to all of these categories. For bulk-data screening, aggregate volumes across covered transactions over the preceding 12 months, because a series of individually small exports can cross a regulatory threshold when combined. Do not automatically exclude a dataset because you have anonymized, pseudonymized, de-identified, or encrypted it.
Before approving an outbound transfer, screen the counterparty, including its owners, employees, and subprocessors, for connections to a country of concern. The result determines whether the rules prohibit, restrict, or exempt the transaction. Restricted vendor, employment, and investment arrangements require security controls such as asset inventories, multifactor authentication, deny-by-default access, centralized logging, encryption in transit and storage, and key management that prevents covered persons from accessing encryption keys.
Your evidence package should connect the covered-data classification, volume calculation, recipient screening, contractual purpose, security assessment, approvals, rejected transactions, and required reports. You can enforce the result through destination allowlists and identity-based access controls, then retain logs long enough to support audits, investigations, and annual reviews.
Brazil's LGPD and Regional Variations
Brazil's LGPD shares several principles with GDPR but has distinct legal bases, transfer mechanisms, and ANPD requirements. Brazil's National Data Protection Authority (ANPD) has approved ANPD-approved SCCs as a mechanism for international transfers. If you rely on SCCs, you must use ANPD's approved clauses, though the LGPD and ANPD framework also permits other transfer mechanisms. If you operate in Brazil, you must monitor regulatory updates, review contracts as needed, and appoint Data Protection Officers (DPOs) where required.
Operationally, start with a transfer inventory that identifies the Brazilian controller, processor, and data subjects, and records the data categories, purpose, destination country, recipient, subprocessors, storage locations, remote-support paths, and retention schedule. Your selected mechanism should match the relationship: adequacy where recognized, contractual clauses for external recipients, or corporate rules for eligible intragroup transfers. Each exception needs an owner, legal basis, expiration date, and review trigger.
Your contract review should confirm that the recipient processes data only for documented purposes, provides information about subprocessors, applies equivalent security and deletion controls, supports data-subject rights, and notifies you of government-access requests when law permits. If you use contractual clauses, manage them as controlled artifacts so conflicting terms, local amendments, or later vendor changes do not silently weaken the approved safeguards. Before execution, confirm that the configured data paths and key custody match the approved transfer decision, and retain the approved contract version and recipient review so changes to vendors, purposes, destinations, or ANPD requirements trigger reassessment.
How Do You Address Asia-Pacific and Global CBPR Requirements?
Use Global CBPR certification as one input to your jurisdiction-by-jurisdiction transfer analysis while local-law review determines the applicable mechanism. Asia-Pacific economies traditionally relied on the voluntary APEC Cross-Border Privacy Rules. In June 2025, the Global CBPR and Global Privacy Recognition for Processors (PRP) systems launched, and the Forum opened participation to interested jurisdictions. While certification remains optional, it provides an interoperable baseline amid rising sovereignty-first laws in China and beyond. Compliance with China's PIPL may require you to store certain personal information in China. It also requires cross-border transfers to follow approved mechanisms without prescribing a specific "region-specific data plane" architecture.
Availability of certification depends on where you are headquartered, and legal recognition varies among participating jurisdictions. Before relying on certification, verify that you and the recipient are eligible, that the recipient's certification is current, and that the certificate covers the entities and processing purposes. Local law must also recognize certification as a sufficient mechanism; in some jurisdictions, it may serve only as evidence of comparable protection. The certification workflow requires an approved accountability agent to assess privacy policies, notices, collection and use limits, access controls, onward-transfer practices, complaint handling, and accountability. If you are a processor, you can use the separate Processor Recognition system, but as a controller, you still need an accurate processor and subprocessor inventory and must confirm that downstream recipients remain within the certified scope.
Treat certification status as machine-readable transfer metadata. Store the accountability agent, certificate scope, covered entities, approval and expiration dates, destination jurisdiction, onward-transfer conditions, and evidence location. Your policy checks should deny or route a transfer for additional review when a certificate expires, a new subprocessor appears, the destination does not recognize the mechanism, or localization rules require an in-country data plane regardless of certification.
Screen each transfer against the applicable regional mechanism, then verify the recipient and required controls.
What Are Your Biggest Compliance Challenges in Global Data Transfers?
Legal conflict, cloud replication, vendor access, performance, and documentation create the main operational risks for your global data transfers:
- Conflicting Legal Requirements Across Jurisdictions: GDPR, Brazil's LGPD, and emerging U.S. national-security rules each impose different legal bases, assessments, and contractual terms. A pipeline that looks lawful in one region can violate another overnight.
- Cloud Architecture and Data Replication Complexity: Multi-cloud configurations can replicate data for resilience, while you may lack complete visibility into where providers store every copy, backup, log, or failover replica. Shadow copies can undermine your compliance efforts when regulations demand that personal data stay inside specific jurisdictions.
- Third-Party Vendor Risk and Limited Visibility: Third-party APIs create blind spots as downstream processors spawn their own transfers. Once data leaves your environment, you rely on contractual guarantees and limited audit rights.
- Performance vs. Compliance Trade-Offs: Keeping data in the right place adds latency that frustrates users and slows analytics. Data localization mandates can force you to duplicate pipelines, inflating infrastructure costs.
- Administrative Burden of Compliance Documentation: Many jurisdictions require paperwork like updated SCCs, DPO appointments, or Transfer Impact Assessments, but these requirements vary widely by region and legal framework.
A unified architecture centralizes your legal-mechanism, destination, and access policies, then enforces them at regional processing boundaries.
How Can You Use Unified Architectures to Simplify Cross-Border Compliance?
Start by separating the "brain" from the "muscle." A unified control plane manages configuration, authentication, and policy globally, while regional data planes keep data, credentials, and compute in-boundary within the jurisdictions that require local processing. The control layer can avoid raw business records.
The control plane may still process personal metadata such as user identifiers, IP addresses, schemas, cursors, logs, timestamps, and telemetry. Remote support access from another country can also constitute a transfer. These flows require their own processor mapping, legal mechanism, access controls, and, for SCC-based transfers, a Transfer Impact Assessment.
How Should You Match Architecture to Workload Risk?
Layered regional data planes are the default for most commercial workloads with residency obligations. They preserve central operations while limiting raw-data movement, and they let you enforce approved regional destinations across every data path. Other designs are defensible depending on the mechanism that applies. Where an adequacy decision or another lawful transfer mechanism covers the recipient, a documented transfer can be preferable to mandatory localization; verify the recipient's status, purpose, onward transfers, and review dates before relying on it. Where the transfer depends on SCCs or BCRs, pair it with a documented Transfer Impact Assessment and supplementary measures, and assess destination law, importer access, key custody, and support access.
Deployment posture then follows the workload. You can run a public control plane with cloud-hosted data planes in specific regions, keep the data plane inside a private VPC for highly regulated workloads, or go further with a full bring-your-own-cloud setup for sovereignty-first workloads. For highly sensitive public-sector workloads, you may instead require an EEA-headquartered provider, EEA-resident operations, and EEA-based subcontractors with access, because U.S. law can reach data under a provider's possession, custody, or control regardless of storage location. When a recipient requires cleartext processing in a third country, treat it as a case-specific legal review: encryption at rest is insufficient once the importer can reach plaintext or keys.
Choose the least restrictive design that still satisfies your applicable transfer mechanism, access, and residency requirements.
How Do You Use Regional Data Planes to Enforce Policy Locally?
Keep a dataset subject to an EU residency policy inside approved EU availability zones. Process Brazilian customer data locally or transfer it under an LGPD mechanism that you record. Apply the relevant national-security controls to covered U.S. workloads. Transfer requests execute only when destination allowlists, legal-mechanism metadata, recipient identity, key-custody requirements, and exception approvals pass policy checks. Each decision should record the policy version, input attributes, result, and evidence location.
How Can You Use Elastic Resource Management to Support Compliance and Scalability?
Elastic resource management adds or removes compute capacity within each regional data plane on demand. This approach responds to traffic spikes without moving data across borders and maintains residency requirements.
- Automated Capacity Management Within Jurisdictions - Kubernetes pod autoscalers and cloud auto-scaling groups add capacity within the configured region, then scale it back when demand subsides. Because only compute changes within the same region, you generally avoid renegotiating SCCs or rerunning Transfer Impact Assessments each time you scale.
- Operational Benefits of Region-Aware Autoscaling - Local scaling reduces processing delay while respecting sovereignty mandates, and you pay for burst capacity only when needed. Routing rules select approved regional destinations, cutting the configuration errors that cause accidental transfers. Fault isolation limits cross-region impact, though shared dependencies can still couple regions.
These benefits depend on configuration that keeps every scaling action within approved regional boundaries.
How Do You Keep Autoscaling Region-Safe?
To keep autoscaling region-safe, pin both compute and persistent storage. The following configuration uses the well-known Kubernetes topology labels that Kubernetes documents in node assignment. It also delays volume provisioning until the scheduler selects an allowed zone, as Kubernetes storage classes describe:
<pre><code>apiVersion: v1
kind: Pod
metadata:
  name: eu-data-plane-worker
spec:
  affinity:
    nodeAffinity:
      requiredDuringSchedulingIgnoredDuringExecution:
        nodeSelectorTerms:
        - matchExpressions:
          - key: topology.kubernetes.io/region
            operator: In
            values: [eu-west-1]
  containers:
  - name: worker
    image: registry.k8s.io/pause:3.8
---
apiVersion: storage.k8s.io/v1
kind: StorageClass
metadata:
  name: eu-regional-storage
provisioner: example.com/example
volumeBindingMode: WaitForFirstConsumer
allowedTopologies:
- matchLabelExpressions:
  - key: topology.kubernetes.io/zone
    values: [eu-west-1a, eu-west-1b]</code></pre>
Other data paths remain unconstrained by this control. CDN and edge caches, cross-region database replicas, backup copies, multi-region audit trails, global API endpoints, and disaster-recovery failover can still move content or metadata elsewhere. Treat each as a separate destination in the transfer inventory, disable automatic cross-region failover where localization is mandatory, and test denied-region deployment attempts before production.
How Should You Govern and Audit Cross-Border Data Transfers?
Governance requires regional controls and an evidence package. Regional controls must pin compute, storage, logs, backups, encryption keys, support access, and failover destinations to approved locations. Your evidence package must connect inventory records, lineage events, policy decisions, recipient and subprocessor identities, legal mechanisms, access records, retention controls, and integrity verification. You can build that package through the following sequence:
- Map Cross-Border Data Flows - Chart every dataset, system, and vendor hop.
- Classify Regulated Data - Tag personal, health, payment, and other sensitive records so you know which laws apply before data leaves a region.
- Deploy Regional Data Planes - Apply location controls and test that they reject deployments and transfer requests to denied regions.
- Automate Policy Enforcement - Use metadata-driven rules to block non-compliant routes, trigger encryption, or require Transfer Impact Assessments.
- Establish Immutable Audit Logs - Centralized, tamper-evident, independently verifiable logs record who accessed what, when, and why.
Build a Centralized Data Inventory and Classification System
Maintain a single source of truth about where sensitive records live, how they move, and who can touch them. Record the dataset owner, sensitivity, data classification, and source jurisdiction. Add the approved destination regions, approved recipient, subprocessors, and transfer mechanism. Include the key custodian and location, retention period, backup location, support-access path, and explicit exception owner.
Maintain a data catalog that tags each dataset with sensitivity and jurisdiction. Continuous discovery tools can surface new tables automatically and support your up-to-date GDPR records of processing.
Capture Complete Lineage and Flow Mapping
Capture hop-by-hop lineage so you can answer "where did this field originate and where did it land?" without digging through code. An OpenLineage event with a column lineage facet can record job information at the event level. The column lineage facet records the output dataset's input dataset namespace, source field, and processing details:
<pre><code>{
"eventType": "COMPLETE",
"eventTime": "2025-09-14T10:00:00.000Z",
"run": {"runId": "01912345-abcd-7000-8000-000000000001"},
"job": {
"namespace": "spark://eu-west-1-cluster",
"name": "anonymise_customer_records"
},
"outputs": [{
"namespace": "s3://eu-datalake",
"name": "processed/customers/anonymised",
"facets": {"columnLineage": {"fields": {
"customer_id_hash": {"inputFields": [{
"namespace": "postgres://eu-db.example.com:5432",
"name": "prod.customers.raw",
"field": "customer_id",
"transformations": [{
"type": "DIRECT",
"subtype": "TRANSFORMATION",
"description": "SHA-256 hash"
}]
}]}
}}}
}]
}</code></pre>Lineage completeness varies by integration. JDBC integrations may omit field types and processing details, dbt multi-query models may retain only the last query ID, and SaaS or API calls may lack request and response dataset descriptions. Document connector coverage, dropped or oversized events, parser errors, and manual evidence for unsupported hops, and describe partial lineage accurately.
Implement Immutable Audit Logs for Regulatory Evidence
Store hash-chained logs in write-once buckets to create tamper-evident records. A relational schema can bind every record to its predecessor while recording a per-stream sequence. In this example, the application transactionally allocates and supplies the next per-stream seq. Your production code must lock the stream head, verify prev_hash, and insert the record in one transaction:
<pre><code>CREATE TABLE audit_log (
  audit_id       BIGINT GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
  stream_id      TEXT        NOT NULL,
  seq            BIGINT      NOT NULL,
  committed_at   TIMESTAMPTZ NOT NULL DEFAULT now(),
  actor_id       TEXT        NOT NULL,
  operation      TEXT        NOT NULL,
  object_type    TEXT        NOT NULL,
  object_id      TEXT        NOT NULL,
  payload        JSONB       NOT NULL,
  payload_sha256 BYTEA       NOT NULL,
  prev_hash      BYTEA       NOT NULL,
  record_hash    BYTEA       NOT NULL,
  writer_sig     BYTEA,
  UNIQUE (stream_id, seq)
);</code></pre>
Verification should recompute each payload hash and record hash, then confirm every prev_hash. It should also detect missing or duplicate sequence values, validate writer signatures, and compare checkpoints held outside the logging system. A hash chain detects alteration, but you may still delete the chain tail or present different histories, so publish checkpoints independently to detect split views.
Write Once, Read Many (WORM) retention also creates a legal tradeoff. Compliance-mode object locks cannot be shortened or bypassed during retention, which supports integrity but can conflict with erasure and storage-limitation obligations. Pseudonymise audit payloads before ingestion, keep direct identifiers out where possible, define a justified retention schedule, and test retrieval and verification. Immutability alone does not prove completeness.
Enforce Policy as Code With Continuous Monitoring
Declarative rules in the control plane block transfers that violate regional rules before they execute. An Open Policy Agent (OPA) residency policy can map each classification to allowed destination regions and return an auditable denial reason:
<pre><code>package data.residency
import future.keywords.if
import future.keywords.contains
allowed_jurisdictions := {
"EU_PERSONAL": {"eu-west-1", "eu-central-1", "eu-west-2"},
"US_FEDERAL": {"us-gov-west-1", "us-gov-east-1"},
"UNRESTRICTED": {"eu-west-1", "eu-central-1", "us-east-1", "us-west-2"}
}
default allow := false
allow if {
input.action == "data_transfer"
classification := input.data_classification
input.destination_region in allowed_jurisdictions[classification]
}
deny contains reason if {
input.action == "data_transfer"
not allow
reason := {
"code": "RESIDENCY_VIOLATION",
"destination_region": input.destination_region,
"data_classification": input.data_classification,
"message": "destination outside allowed jurisdiction for this data classification"
}
}</code></pre>Record the input, decision, policy and bundle version, requester, and execution result. Fail-closed enforcement preserves residency controls when the policy service stops responding, but it can stop legitimate pipelines. Fail-open behavior preserves availability but permits unreviewed transfers. High-risk data should default to denial; use locally cached signed policies, health checks, and a time-limited emergency exception that names an approver and produces an audit event. Because policies live in code, you can unit-test them and roll out changes globally in minutes, while event-level monitoring exposes anomalies such as a spike in exports to a non-adequate country and triggers immediate alerts instead of quarterly surprises.
As a hypothetical architecture walkthrough, consider processing a multinational bank's card transactions in Frankfurt, Tokyo, and São Paulo. Region-aware data planes keep raw Payment Card Industry (PCI) data local. Redacted aggregates flow to a U.S. analytics lake only after automated lineage checks pass and systems seal the logs.
How Does Airbyte Flex Help With Cross-Border Data Transfer Compliance?
Airbyte Flex applies these controls through customer-operated processing boundaries, outbound-only networking, and regional deployment options.
Hybrid Architecture Keeps Records In-Boundary
Airbyte Flex uses a hybrid control plane to manage 700+ connectors, while you operate regional data planes in your own VPCs or on-premises servers on AWS, GCP, and Azure.
Airbyte operates the control plane, which stores only configuration and metadata such as cursor and primary-key values (and, during development with Connector Builder, some data). Every other record stays inside your customer-operated data planes. Airbyte's open-source foundation and customer-operated data planes give you control over deployment location.
Outbound-Only Communication Reduces Exposure
Communication flows outbound-only. Each data plane initiates an encrypted session to the control plane. This design removes the need to expose inbound connections to your data plane and reduces the network attack surface. Airbyte's hybrid control plane manages configuration and policy globally while your customer-operated data planes keep replication in configured jurisdictions. You remain responsible for determining and meeting your regulatory obligations.
Flexible Deployment Supports Regional Workloads
You can run public cloud data planes for standard workloads, run private clusters for HIPAA or LGPD datasets, or use full on-premises deployments, and mix these options as demand changes. You can sync EU sales data to analytics warehouses through an EU-only plane, Japanese inventory streams through a Tokyo plane, and US marketing events stateside, all managed from one UI. The same replicated records are what an in-boundary retrieval stack indexes, so agent reads inherit the boundary and access controls the pipeline already enforces.
Where Should You Start Your Compliance Modernization Journey?
The expensive cross-border failures come from transfers nobody mapped and trust relationships nobody reviewed, not from storage regions nobody configured. Once your inventory shows how much authority crosses each boundary, the compliance question turns into an architecture decision you can test against denied-region deployments and real audit queries.
Airbyte covers that range, from a fully managed cloud service to Flex, which keeps execution, credentials, and compute inside your environment while Airbyte runs orchestration. Validate your transfer inventory, approved mechanisms, and regional processing boundaries against your configured data paths before you scale.
Get a demo to walk through how Flex would deploy regional data planes across your jurisdictions without opening inbound access or exposing raw records.
Frequently Asked Questions
How Do You Distinguish GDPR Adequacy Decisions From Standard Contractual Clauses?
Adequacy decisions are formal EU determinations that a third country offers essentially equivalent protection, so transfers proceed without additional safeguards. SCCs are contractual commitments used when no adequacy decision exists. They require you to assess whether destination-country law and practice undermine those safeguards, and to add supplementary measures where needed.
How Do You Use Regional Data Planes for Cross-Border Data Transfer Compliance and Localization Requirements?
Regional data planes process data within specific geographic boundaries while the control plane orchestrates operations globally. They support localization for covered data in jurisdictions such as China or Russia and management of regulated international transfers in jurisdictions such as Brazil, with the legal basis for a transfer established separately from the technical enforcement. You keep centralized governance and visibility without rebuilding integration logic for each geography.
When Do You Need Transfer Impact Assessments Under GDPR?
If you rely on Article 46 safeguards, including SCCs or Binding Corporate Rules, you must assess and document whether destination-country law and practice undermine those safeguards, with supplementary measures where necessary. This is particularly important for countries with broad government surveillance powers or inadequate legal protections.
Can Your Elastic Scaling Within Regional Data Planes Trigger Compliance Violations?
Properly configured regional data planes scale compute resources within the same approved jurisdiction without moving data. You must ensure your cloud provider locks its auto-scaling configuration to the region and cannot fail over to other geographies. Misconfigured multi-region replication, backup, CDN, global endpoint, or failover settings can move content or metadata across regional boundaries during scaling and recovery events.
Integrate with 700+ apps using Airbyte
Move data from 700+ sources into warehouses, lakes, and beyond. Set up pipelines in minutes with pre-built connectors and the Connector Builder.