Best Practices for Deployments with Large Data Volumes
Learn best practices for deploying large data volumes efficiently, ensuring optimized performance during deployments.
Reliable deployments with large data volumes require measured capacity limits, an appropriate sync mode, staged validation, idempotent retries, and explicit boundaries for data, credentials, and compute. Worldwide data volumes are growing, while measured source, network, worker, and destination constraints determine whether a deployment will scale.
Separate systems create data silos that complicate data management and hide bottlenecks. Data integration tools consolidate data from diverse sources in your target system. This centralized view exposes bottlenecks across the full path so you can control throughput, integrity, cost, and deployment boundaries.
TL;DR
These four practices summarize the requirements for reliable large-volume deployments.
- Deployments with Large Data Volumes work best when you measure source, network, worker, and destination limits before adding parallelism.
- Choose full refresh, cursor incremental, or CDC according to table size, freshness, delete handling, and source-log retention.
- Stage and validate large loads, make retries idempotent, and reconcile equivalent source and destination boundaries before promotion.
- Decide where data, credentials, and compute may run so your deployment meets performance, governance, and sovereignty requirements.
Understanding Large Data Volume Scenarios
Large data volumes place sustained demand on source connections, network throughput, worker memory and temporary disk, and destination concurrency. Data silos obscure bottlenecks and produce incomplete analysis, which can hinder decisions and system performance. Managing these constraints across on-premises and cloud environments requires hybrid data management.
Healthcare data, for example, includes electronic health records and data from wearable devices.
What Are the Key Considerations for Large-Scale Data Deployments?
Large-scale deployments must balance measured scalability and performance requirements with data integrity, consistency, cost, and resource constraints.
Scalability and Performance Requirements
Scale your system against measured throughput, record size, memory, temporary disk, source connections, and destination concurrency. Choose a database or processing framework that can expand through horizontal scaling, which adds more servers, or vertical scaling, which upgrades existing hardware. Use indexing and caching where query plans and workload measurements show that they reduce response times.
Data Integrity and Consistency Challenges
You must protect data integrity and consistency when managing large data workloads. Use validation techniques such as input checks and anomaly detection to prevent errors and data corruption. Establish a data governance framework to uphold integrity standards.
Cost-Effectiveness and Resource Management
Evaluate storage and processing platforms by measuring bytes extracted, bytes transferred, destination compute time, retained logs, and temporary storage for each workload. Cloud services can provide flexibility and scalability, but moving data across regions or availability zones can add network cost and latency. Keep sources, workers, and destinations in compatible regions when governance requirements allow it.
Allocate resources from measured throughput because record count alone does not capture resource demand. A workload with large JSON records may consume more memory, network bandwidth, and destination write capacity than a pipeline moving many narrow rows. Regularly compare allocated CPU, memory, temporary disk, source connections, and destination concurrency with actual utilization so that scaling one layer does not simply move the bottleneck to another.
What Are the Essential Features for Handling Large Data Volumes with Airbyte?
Replication platforms support sources and destinations through connectors, configurable sync modes, scheduling, and orchestration integrations. A Kubernetes-compatible architecture can support scalable and resilient deployments. Match these features to measured workload constraints because no single configuration fits every large-volume deployment.
Replication Mechanics
Incremental Synchronization Capabilities
Replication platforms support incremental synchronization options that let you replicate only the data that has changed since the last sync. Do not use an auto-incrementing ID as a cursor to detect updates because the ID does not change when the row changes. Index timestamp cursors and require non-null values.
Re-read a bounded lookback window to capture late-arriving updates and clock skew, then deduplicate at the destination. If the source performs hard deletes or does not reliably update the cursor, prefer log-based CDC or schedule key-set reconciliation.
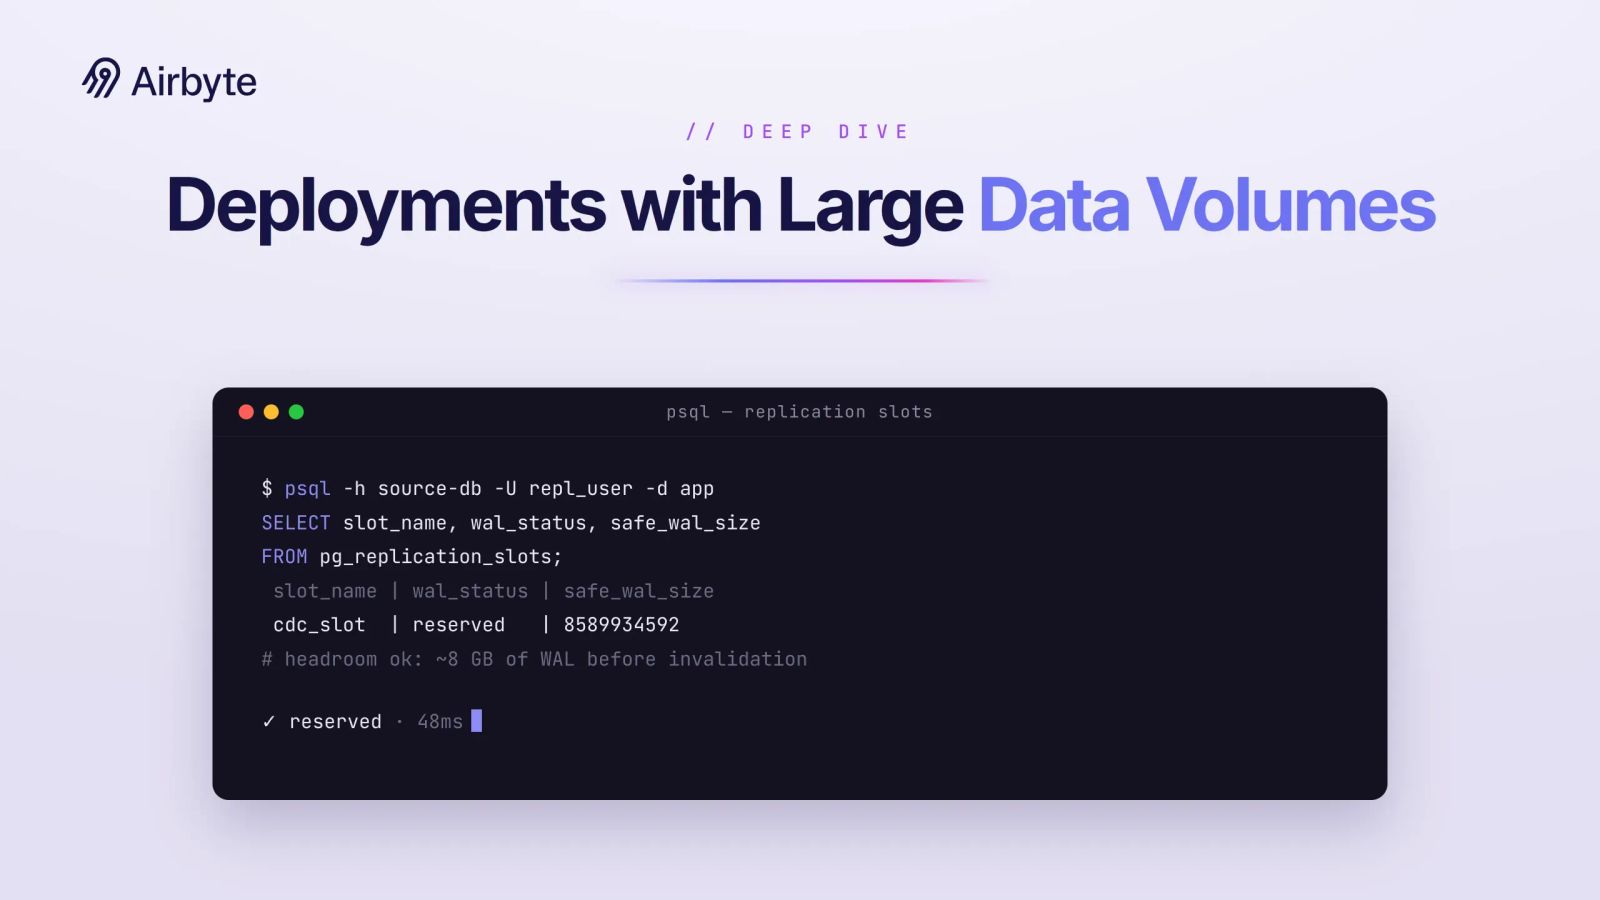
CDC captures committed changes from transaction logs, but it introduces retention obligations. For PostgreSQL 18, monitor restart_lsn, wal_status, and safe_wal_size in pg_replication_slots. The restart_lsn value records the oldest log sequence number (LSN) that the slot still needs, wal_status reports retention state, and safe_wal_size estimates how much write-ahead log (WAL) the source can add before the slot risks invalidation.
Set a finite max_slot_wal_keep_size when uncontrolled WAL growth creates more risk than rebuilding an invalidated slot. For MySQL, set binlog_expire_logs_seconds longer than the maximum expected replica or connector outage or lag, with an operational safety margin. Begin a coordinated snapshot from a known log position so the process neither loses writes committed during the snapshot nor applies them in the wrong order.
<pre><code>SELECT slot_name,
       pg_wal_lsn_diff(pg_current_wal_lsn(), restart_lsn) AS wal_retained_bytes,
       wal_status,
       safe_wal_size,
       inactive_since,
       invalidation_reason
FROM pg_replication_slots;</code></pre>
Treat replication as at-least-once unless every source, transport, checkpoint, and destination supports stronger semantics across the full pipeline. A source change position identifies an event's ordered location in the transaction log. Establish CDC completeness with independent point-in-time counts, aggregates, partition hashes, and targeted row comparisons.
The correct mode depends on table size, freshness requirements, source permissions, and whether you must capture deletes.
Use the least complex sync mode that still meets your correctness, freshness, and delete-handling requirements.
Parallel Processing and Multi-Threading
A workload-based architecture and configurable worker concurrency support concurrent data synchronization tasks. This capacity accommodates larger data volumes. The architecture separates scheduling and orchestration from core data movement so you can control data jobs and worker concurrency independently.
Data Processing Controls
Data Normalization and Processing Techniques
You can run SQL, dbt (data build tool), or Python processing steps downstream of replication syncs and coordinate them through your orchestration layer. For incremental models, define a stable unique_key when late-arriving records may update rows already loaded. Schema changes do not necessarily populate historical records with values for newly added columns. Plan an explicit backfill or full refresh when you must populate historical values, and test processing steps against staged data before promoting them to production tables.
Flexible Scheduling Options
Scheduled syncs run at recurring intervals, cron syncs use custom expressions for precise timing, and Manual Syncs start through the UI or API.
Choose an interval that exceeds normal job duration or enforce a concurrency limit so that one run cannot overlap the next and compete for the same source connections or destination merge slots. Manual syncs are useful for controlled validation and recovery, but recurring production workloads should use monitored schedules with duration and freshness alerts.
Record Change History
This feature records supported modifications to problematic rows in transit. If an oversized or invalid record requires a supported modification, the system logs the change so operators can review how it handled the record.
Row-size limits vary by destination and ingestion path, so the source may accept a record that still exceeds the destination’s parser, row, or semi-structured data limit. A completed sync confirms transport success. Analytical use of every modified record requires separate validation. Review logged changes, quarantine incompatible records when necessary, and compare rejected or modified-record counts before promoting staged data.
Operational Coordination
Pipeline Orchestration
Replication platforms integrate with data orchestration tools like Apache Airflow, Dagster, Prefect, and Kestra.
Use the orchestrator to enforce source and destination concurrency limits, persist run identifiers, and trigger validation only after a sync reaches a durable checkpoint. Retries should resume from the checkpoint associated with the tracked run identifier.
What Are the Best Practices for Large-Scale Data Integration?
The best practices are to size infrastructure from representative workloads, control transfer and destination concurrency, stage large loads, make retries idempotent, and validate data before promotion.
Capacity and Transfer Controls
Proper Infrastructure Sizing and Resource Allocation
When integrating large-scale data, size infrastructure from a representative load test. Measurements should include average and peak bytes per second, average and maximum record size, memory per worker, temporary-disk growth, source connections per task, and destination concurrency. These measurements determine the parallelism needed to finish within the load window. The tightest source, network, destination, available partitions, or metadata or commit serialization constraint sets the operational cap.
For Kubernetes Guaranteed QoS, every container in the pod must define CPU and memory requests and limits, and each request must equal its corresponding limit. Kubernetes evicts this configuration less often than Burstable or BestEffort workloads under node pressure. Kubernetes reports exit code 137 and reason OOMKilled when a container exceeds its memory limit.
For Java Virtual Machine (JVM) workers, keep heap below the container limit because thread stacks, metaspace, direct buffers, and other off-heap allocations also consume memory. Reserve non-heap headroom based on observed usage, then adjust it from measurements.
Temporary files, spill, and buffered records also need explicit capacity. A tmpfs-backed emptyDir counts against memory, while disk-backed temporary storage can trigger node storage pressure. Monitor both and set workload-specific limits. Finally, reserve database connections for application and administrative traffic. Worker parallelism must not consume every available source connection or exceed destination merge concurrency.
If destination queues or merge times are already increasing, more extraction workers will amplify the bottleneck without resolving it.
Network Configuration Improvements
Quality of Service (QoS) settings can prioritize critical data flows and allocate bandwidth to them.
For long-distance transfers, the Transmission Control Protocol (TCP) bandwidth-delay product also constrains throughput. With a 4 MB socket buffer and 100 ms round-trip time, a single connection can carry only about 40 MB per second even when the underlying link is faster. Size send and receive buffers to at least bandwidth multiplied by round-trip time, and use multiple flows only when the source and destination can sustain them. Compress records when CPU capacity is available. Keep sources, workers, and destinations on direct, region-compatible network paths where governance permits to reduce latency, cross-zone traffic, and avoidable egress processing.
Storage and Load Controls
Implementing Effective Data Partitioning Strategies
Data partitioning divides large datasets into smaller, easier-to-manage partitions. It speeds up query execution because queries can scan specific subsets and avoid the whole database.
You can partition data by rows (horizontal), by columns (vertical), or according to operational needs (functional partitioning). Choose a partition key that supports the dominant query and load patterns. Time-based partitioning works well for append-heavy event data, while hash partitioning can distribute writes when a time partition would create a hot partition. Avoid excessive partition counts because metadata and small-file overhead can offset pruning benefits.
Efficient Load Balancing and Job Scheduling
Schedule large backfills separately from freshness-sensitive incremental jobs, and apply concurrency limits at both the source and destination. These controls preserve the connections, memory, and merge slots required by current data.
Index Strategically to Improve Performance
Custom indexes can improve query performance on large datasets for databases and platforms like Salesforce. Focus on fields that queries use in filters, joins, or sorting operations, especially in frequently executed queries.
Existing indexes may cover common key fields. You may need to configure additional indexes for frequently filtered custom fields through the platform’s supported process.
Evaluate filter selectivity against the current index type, table size, and query plan. Predicates involving negation, leading wildcards, broad disjunctions, null comparisons, or calculated values may prevent efficient index use, so test them against representative data and revise the extraction strategy when scans remain excessive.
Platform-Specific Load Controls
Use the loading pattern that matches each destination's storage and concurrency behavior.
Streaming destinations need a separate compaction schedule because ingestion alone does not produce query-efficient storage. Copy-on-write rewrites affected files during updates and favors read-heavy tables. Merge-on-read records changes separately and applies them during reads or compaction, which can favor write-heavy tables.
Use destination queue depth, merge duration, and validation results to set throttling and promotion criteria before increasing parallelism.
Use Skinny Tables to Reduce Load
Skinny tables can contain a subset of frequently accessed fields. Storing a subset of fields in one physical table can reduce query run time, especially in environments with large amounts of records.
Skinny tables work well in high-read use cases, but you should update them cautiously to protect data integrity. Where a platform supports skinny tables, provisioning and environment availability may require administrative coordination. Treat skinny tables as a targeted, short-term query improvement for large objects. Selective queries, indexing, archiving, and an appropriate long-term data model remain necessary.
Apply Batch Processing for Data Loads
When working with large volumes of source data, use supported batch or bulk-loading interfaces. These approaches break down operations into manageable jobs and reduce timeouts.
For warehouse and lakehouse destinations, write batches to staging before modifying production tables. Create multiple similarly sized staged files so the destination can load them in parallel, but avoid producing many tiny files. Deduplicate each batch by primary key and the latest source change position before MERGE; otherwise, multiple source rows can match one target row or duplicates can enter the destination. Limit concurrent merges on the same target table, partition large targets by common filters, and compact small files after sustained streaming loads.
<pre><code>WITH latest_change AS (
  SELECT *,
         ROW_NUMBER() OVER (
           PARTITION BY primary_key
           ORDER BY extracted_at DESC, _cdc_lsn DESC
         ) AS row_number
  FROM landing_events
)
SELECT *
FROM latest_change
WHERE row_number = 1;</code></pre>
Persist a batch ID or source position with each write so retries are idempotent. When using batch tools, track system performance and job completion rates to avoid overloading processing queues.
Review Sharing Rules and Calculations
In platforms with sharing rules and calculated fields, formula evaluation and access recalculation can significantly affect data load time and system speed. Limit complex calculated fields on objects with large data volumes. Document and simplify data access strategies to reduce access-policy inconsistencies and recalculation work.
Watch for ownership, parent-child, and lookup skew. Contention risk increases when one owner, parent, or lookup record holds a heavy concentration of records. Where supported, deferred sharing calculations can pause recalculation during large maintenance loads, but administrators must resume sharing and initiate a full recalculation afterward. Sort bulk-load batches by the related parent key and avoid peak business hours. Retry lock errors, and prevent concurrent batches from updating the same related record groups.
How Can You Monitor and Maintain Large Data Deployments?
Monitor large deployments by separating availability from correctness and tracking source lag, worker resources, destination capacity, freshness, schema drift, retries, and reconciliation results against workload-specific baselines.
1. Establish Clear Monitoring Metrics
Define key performance indicators (KPIs) critical for your data operations, such as latency, throughput, and error rates. You can connect your replication platform with monitoring tools like Datadog and OpenTelemetry to track and analyze your data pipelines. Use automated tools that monitor resource usage as work runs.
Separate pipeline availability from data correctness. Connector uptime and throughput show whether work is progressing, while freshness, duplicate, schema, and reconciliation checks show whether the destination is trustworthy.
Use these signals to connect symptoms with the layer most likely to require attention.
Respond to the constrained layer instead of scaling every component at once. Change one component at a time so you can verify the result.
2. Use MPP Databases for Scalability
Massively Parallel Processing (MPP) databases, such as Amazon Redshift and Google BigQuery, distribute queries across multiple nodes to improve performance. Measure destination concurrency, queue depth, and merge duration to determine whether that capacity shortens load windows or shifts the bottleneck.
That destination capacity only improves deployment performance when scheduling, checkpoints, and lag monitoring keep replication loads controlled.
3. Automate Data Replication
Automate the configured replication workflow and monitor it for failures, lag, and expired source positions.
Backups protect recoverability, while replication provides a current copy. Maintain both controls.
4. Monitor Logs
Because automated workflows can retry or resume without direct operator involvement, logs must connect each attempt to its source and destination state. Use connector logs for data reporting and synchronization. Correlate them with source positions, durable checkpoints, retry counts, worker restarts, and destination batch IDs so you can trace an apparently successful retry across every stage. Alert on repeated authentication or schema errors and destination rejects. Retain enough log history to distinguish a transient slowdown from a checkpoint rollback, repeated batch, or retention window that is close to expiring.
5. Conduct Data Quality Checks
Automate data accuracy, completeness, and consistency checks before and after transfers, and reconcile in stages so billion-row comparisons remain practical. Enforce non-null primary and cursor keys, and quarantine incompatible schema changes before promotion.
Start with row counts for the same point-in-time boundary. If they differ, compare partition-level counts and key ranges. If counts match, compare aggregates such as SUM, MIN, MAX, and null counts.
Next, compare deterministic hashes by partition or key range. Use row-level comparisons only for the partitions that differ.
<pre><code>-- Run against equivalent source and destination snapshots.
SELECT COUNT(*) AS row_count,
MIN(updated_at) AS min_updated_at,
MAX(updated_at) AS max_updated_at,
SUM(CASE WHEN primary_key IS NULL THEN 1 ELSE 0 END) AS null_keys
FROM replicated_table;
-- PostgreSQL partition or table hash ordered by primary key; use explicit NULL handling and separators/encoding to avoid ambiguous row hashes.
SELECT md5(string_agg(row_hash, '' ORDER BY primary_key)) AS table_hash
FROM (
SELECT primary_key,
md5(coalesce(col1::text, '<NULL>') || '|' || coalesce(col2::text, '<NULL>')) AS row_hash
FROM replicated_table
) AS hashed_rows;</code></pre>Run reconciliation at a consistent source position when possible. A live source can change between two queries. These changes can cause false mismatches. Retain reconciliation results, the source watermark, and the destination batch or checkpoint used for each comparison.
6. Continuously Monitor Query and Sync Patterns
Track query run times and log database bottlenecks so you can identify recurring queries on non-indexed fields and sync operations that repeatedly fail or slow down due to data volume spikes.
Capture query plans, estimated cardinality, rows scanned, rows returned, and filter selectivity. Duration alone cannot identify the cause. A query that returns few rows after scanning most of a large object needs a more selective indexed predicate, a narrower date or key range, or a different extraction strategy. On platforms that enforce selectivity requirements for large objects, compare filters with the applicable standard and custom index guidance. Connector logs and observability integrations can pinpoint slow syncs, schema drift, and connector-specific errors.
7. Audit Data Relationships and Dependencies
Monitor foreign key relationships, especially in environments with multiple related objects. Maintaining data integrity across linked records takes more time as data volume grows without clear constraints or indexing.
Map out master-detail or lookup relationships that affect data load performance. Use the relationship map to order parent loads before dependent children, identify cascades that enlarge transactions, and define lock domains that teams must not update concurrently. Where ownership, parent-child, or lookup skew becomes significant, sort batches by the related key and sequence those groups to reduce record-lock contention.
8. Flag Slow Sandbox Refreshes and Test Environments
Sandbox refreshes often slow down when you handle large data volumes in staging or test environments. Where possible, use synthetic data or smaller datasets for testing, and document data subsets used in test jobs to replicate production issues effectively.
Keep test subsets referentially complete. Preserve production-like distributions for record size, null frequency, key skew, partition density, schema variation, and parent-child fan-out. Mask or synthesize sensitive fields before loading them into lower environments. Test the same oversized records, schema changes, lock-prone relationship groups, and partition boundaries that affect production. Then benchmark with production-equivalent worker limits and destination concurrency. Also verify that the test environment supports any platform-specific query improvements required in production.
9. Track Long-Running Jobs and Sync Failures
Monitor job duration, retry frequency, and connector-level metrics. Alert when syncs exceed threshold durations or when data sets in transit fail to match schema expectations.
Set thresholds from a rolling median and high-percentile duration for comparable workloads. One fixed limit cannot represent every table. When a run exceeds its baseline, use the monitoring signals above to identify the constrained layer before adding capacity. Resume a stalled job from the last durable checkpoint associated with its run identifier so it does not restart an untracked full load. Set up alerts for batch jobs, data replication tasks, or streaming syncs that become delayed or stalled due to schema issues, permission changes, or infrastructure strain.
10. Use Big Objects or Archive Strategies for Infrequently Accessed Data
In Salesforce environments, you can use Big Objects to store historical or rarely queried large amounts of data. Consider a similar archival or tiered storage strategy for systems managing large datasets.
Define the archive’s access path, index strategy, retention policy, and supported loading and extraction methods before moving data. Use supported bulk or batch interfaces for large processing workflows, and test their limits against representative data volumes.
Choose archival when you must retain data and keep it occasionally accessible but do not need fast joins, frequent updates, or routine replication. Keep actively queried recent partitions in the operational system. Move older immutable records to the archive according to retention and legal-hold policies. Keep archived data accessible through external queries or APIs, but do not involve it actively in critical sync jobs.
What Is the Relationship of Data Governance and Compliance With Large Data Volumes?
Data governance defines the policies and processes that protect data quality, security, and availability. Compliance applies requirements such as GDPR and HIPAA to your source, pipeline, destination, access, retention, and contractual architecture.
As data volumes grow, protecting sensitive information and meeting compliance standards become increasingly complex. Before deployment, classify the data because its classification determines the approved regions for sources, workers, staging, destinations, backups, and archives. Those boundaries define where data, credentials, and compute may run and which components your organization must keep in-boundary within its controlled environment. For international transfers involving personal data, identify the applicable transfer mechanism. Then assess whether the destination location and access model meet organizational requirements.
Use an architecture checklist that covers:
- Data classification and fields that you must exclude, tokenize, hash, or mask before loading.
- Approved source and destination regions, including temporary files, logs, backups, and disaster-recovery copies.
- Encryption in transit and at rest, key ownership, key rotation, and who can decrypt the data.
- Role-based access, privileged-access logging, audit retention, and periodic access reviews.
- Retention schedules, legal holds, archive policies, and deletion propagation from source to replicas.
- Processor, business associate, and subcontractor obligations, including data location and incident notification terms.
- Destination controls, because pipeline security does not compensate for an over-permissive warehouse, lake, retrieval store, or API.
For HIPAA-regulated workloads, distinguish required safeguards from addressable implementation specifications. The current HIPAA Security Rule requires transmission security, while encryption and decryption specifications are addressable and require evaluation and documentation. Business associate obligations must also extend through applicable subcontractors.
For GDPR-regulated workloads, masking or pseudonymization can reduce exposure but does not by itself satisfy lawful processing, transfer, retention, access, or deletion obligations. You still need controls for each of those obligations.
Audit logging, encryption in transit and at rest, and personally identifiable information (PII) masking can support security and compliance programs. These controls support a compliance program only when the complete source, pipeline, destination, access, retention, and contractual architecture governs deployment boundaries and future scaling decisions.
How Airbyte Flex Helps With Deployments With Large Data Volumes
Airbyte Flex supports a hybrid deployment model for organizations that need data movement, credentials, and compute to remain in-boundary. Its hybrid control plane separates Airbyte-managed orchestration from the customer-controlled data plane while managing replication across cloud, VPC, and customer-controlled environments, including on-premises physical hardware where required.
This deployment fit sits on a broader sovereignty spectrum: managed cloud, Flex hybrid deployment, self-managed infrastructure, and air-gapped environments. Choose the position that fits your residency, network, credential, operational, and governance requirements.
Airbyte provides an open-source foundation and a library of 700+ connectors. Airbyte Flex supports the same replication connector catalog for moving data across controlled infrastructure.
Airbyte Flex also provides audit logging, encryption in transit and at rest, and personally identifiable information (PII) masking to support security and compliance programs. Governed replication can also keep downstream retrieval stores, agent context, and AI data products current within those controls.
How Can You Simplify Large Data Deployments with Airbyte?
Begin with a representative load test, identify measured bottlenecks, and define validation and promotion criteria before scaling the deployment with Airbyte. Get a demo to see how Airbyte Flex deploys the replication connector catalog in your boundary.
Frequently Asked Questions
How Should You Size Deployments With Large Data Volumes?
Size your deployment from representative throughput, record size, memory, temporary disk, connection, and destination concurrency measurements. Increase workers only while the source, network, and destination retain enough capacity.
Which Sync Mode Should You Use for Deployments With Large Data Volumes?
Use full refresh for small or replaceable tables, cursor incremental for reliable monotonic cursors, and CDC when you must capture deletes or frequent changes. Account for source-log retention, duplicate delivery, and coordinated snapshots before choosing CDC.
How Do You Protect Data Integrity During Large Deployments?
Load data into staging and compare equivalent source and destination boundaries before promotion. Check row counts, aggregates, null keys, duplicates, schema compatibility, and deterministic hashes, then retain the source watermark and destination batch ID.
How Do Deployment Boundaries Affect Large Data Volumes?
Your boundary determines where data, credentials, compute, temporary files, logs, backups, and archives may run. Document these locations before deployment so performance decisions remain consistent with residency, security, and compliance requirements.
Integrate with 700+ apps using Airbyte
Move data from 700+ sources into warehouses, lakes, and beyond. Set up pipelines in minutes with pre-built connectors and the Connector Builder.